Overview
This is a revised write-up of my three-node Proxmox VE cluster. Since the first version of this post, the network design has been simplified, the backup design has changed a lot, and I’ve learned a few things the hard way. Host names, addresses and VLAN numbers are left out or generalised.
The design goals haven’t changed:
- Logical traffic isolation on modest hardware
- Shared storage, so key services can fail over between nodes
- Predictable behaviour under load
- Operational simplicity over benchmark numbers
The cluster now runs 20 guests: 19 unprivileged LXC containers and one VM. Most guest disks live on a shared iSCSI LUN on a Synology NAS. Everything is on UPS power.
Hardware Platform
Each node is an HP EliteDesk 800 G2 Mini (the 35 W version, a 4-core i5-6500T) with:
- Mixed RAM. The smallest node has a quarter of the RAM of the largest.
- An NVMe or SATA SSD system disk, and on two nodes a second SATA SSD
- A single 1 GbE NIC
These machines are quiet, sip power, and are cheap on the second-hand market. The RAM imbalance matters more than I expected, as you’ll see in the HA section.
Shared storage is a Synology DS414. It provides an iSCSI LUN for guest disks, an NFS export for backups, and an SMB share for media.

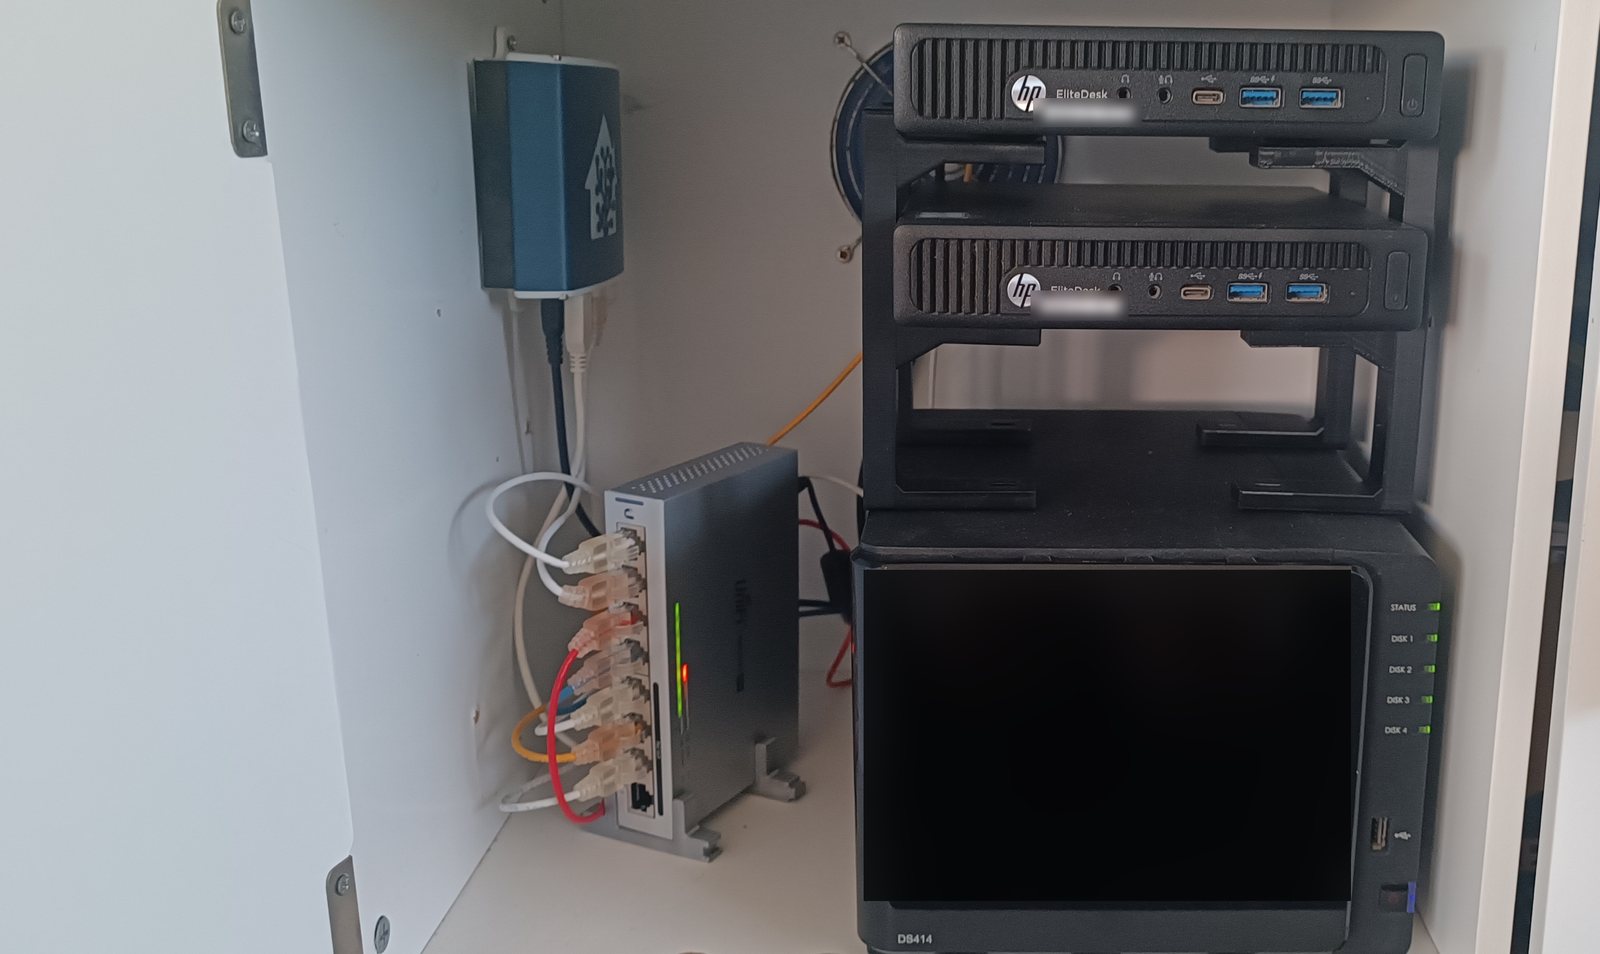
Two of the nodes live in a cupboard on stacking stands above the NAS, which keeps the cabling short and the front panels in reach. The 8-port PoE switch beside them carries the NAS, both nodes and the Home Assistant box, and runs one trunk back to the core switch.
Network Design
Every node has one NIC. Every VLAN is a tagged sub-interface of that NIC, bridged into its own Proxmox bridge. The node-facing networks are:
| Network | Purpose |
|---|---|
| Management | Proxmox hosts, primary cluster (corosync) link |
| Servers | Most guests |
| Development | My dev container |
| Storage | iSCSI guest disks, SMB, UPS (NUT), local backup traffic, secondary corosync link |
| Backup storage | NFS backups to the NAS |
| DMZ | The public reverse proxy |
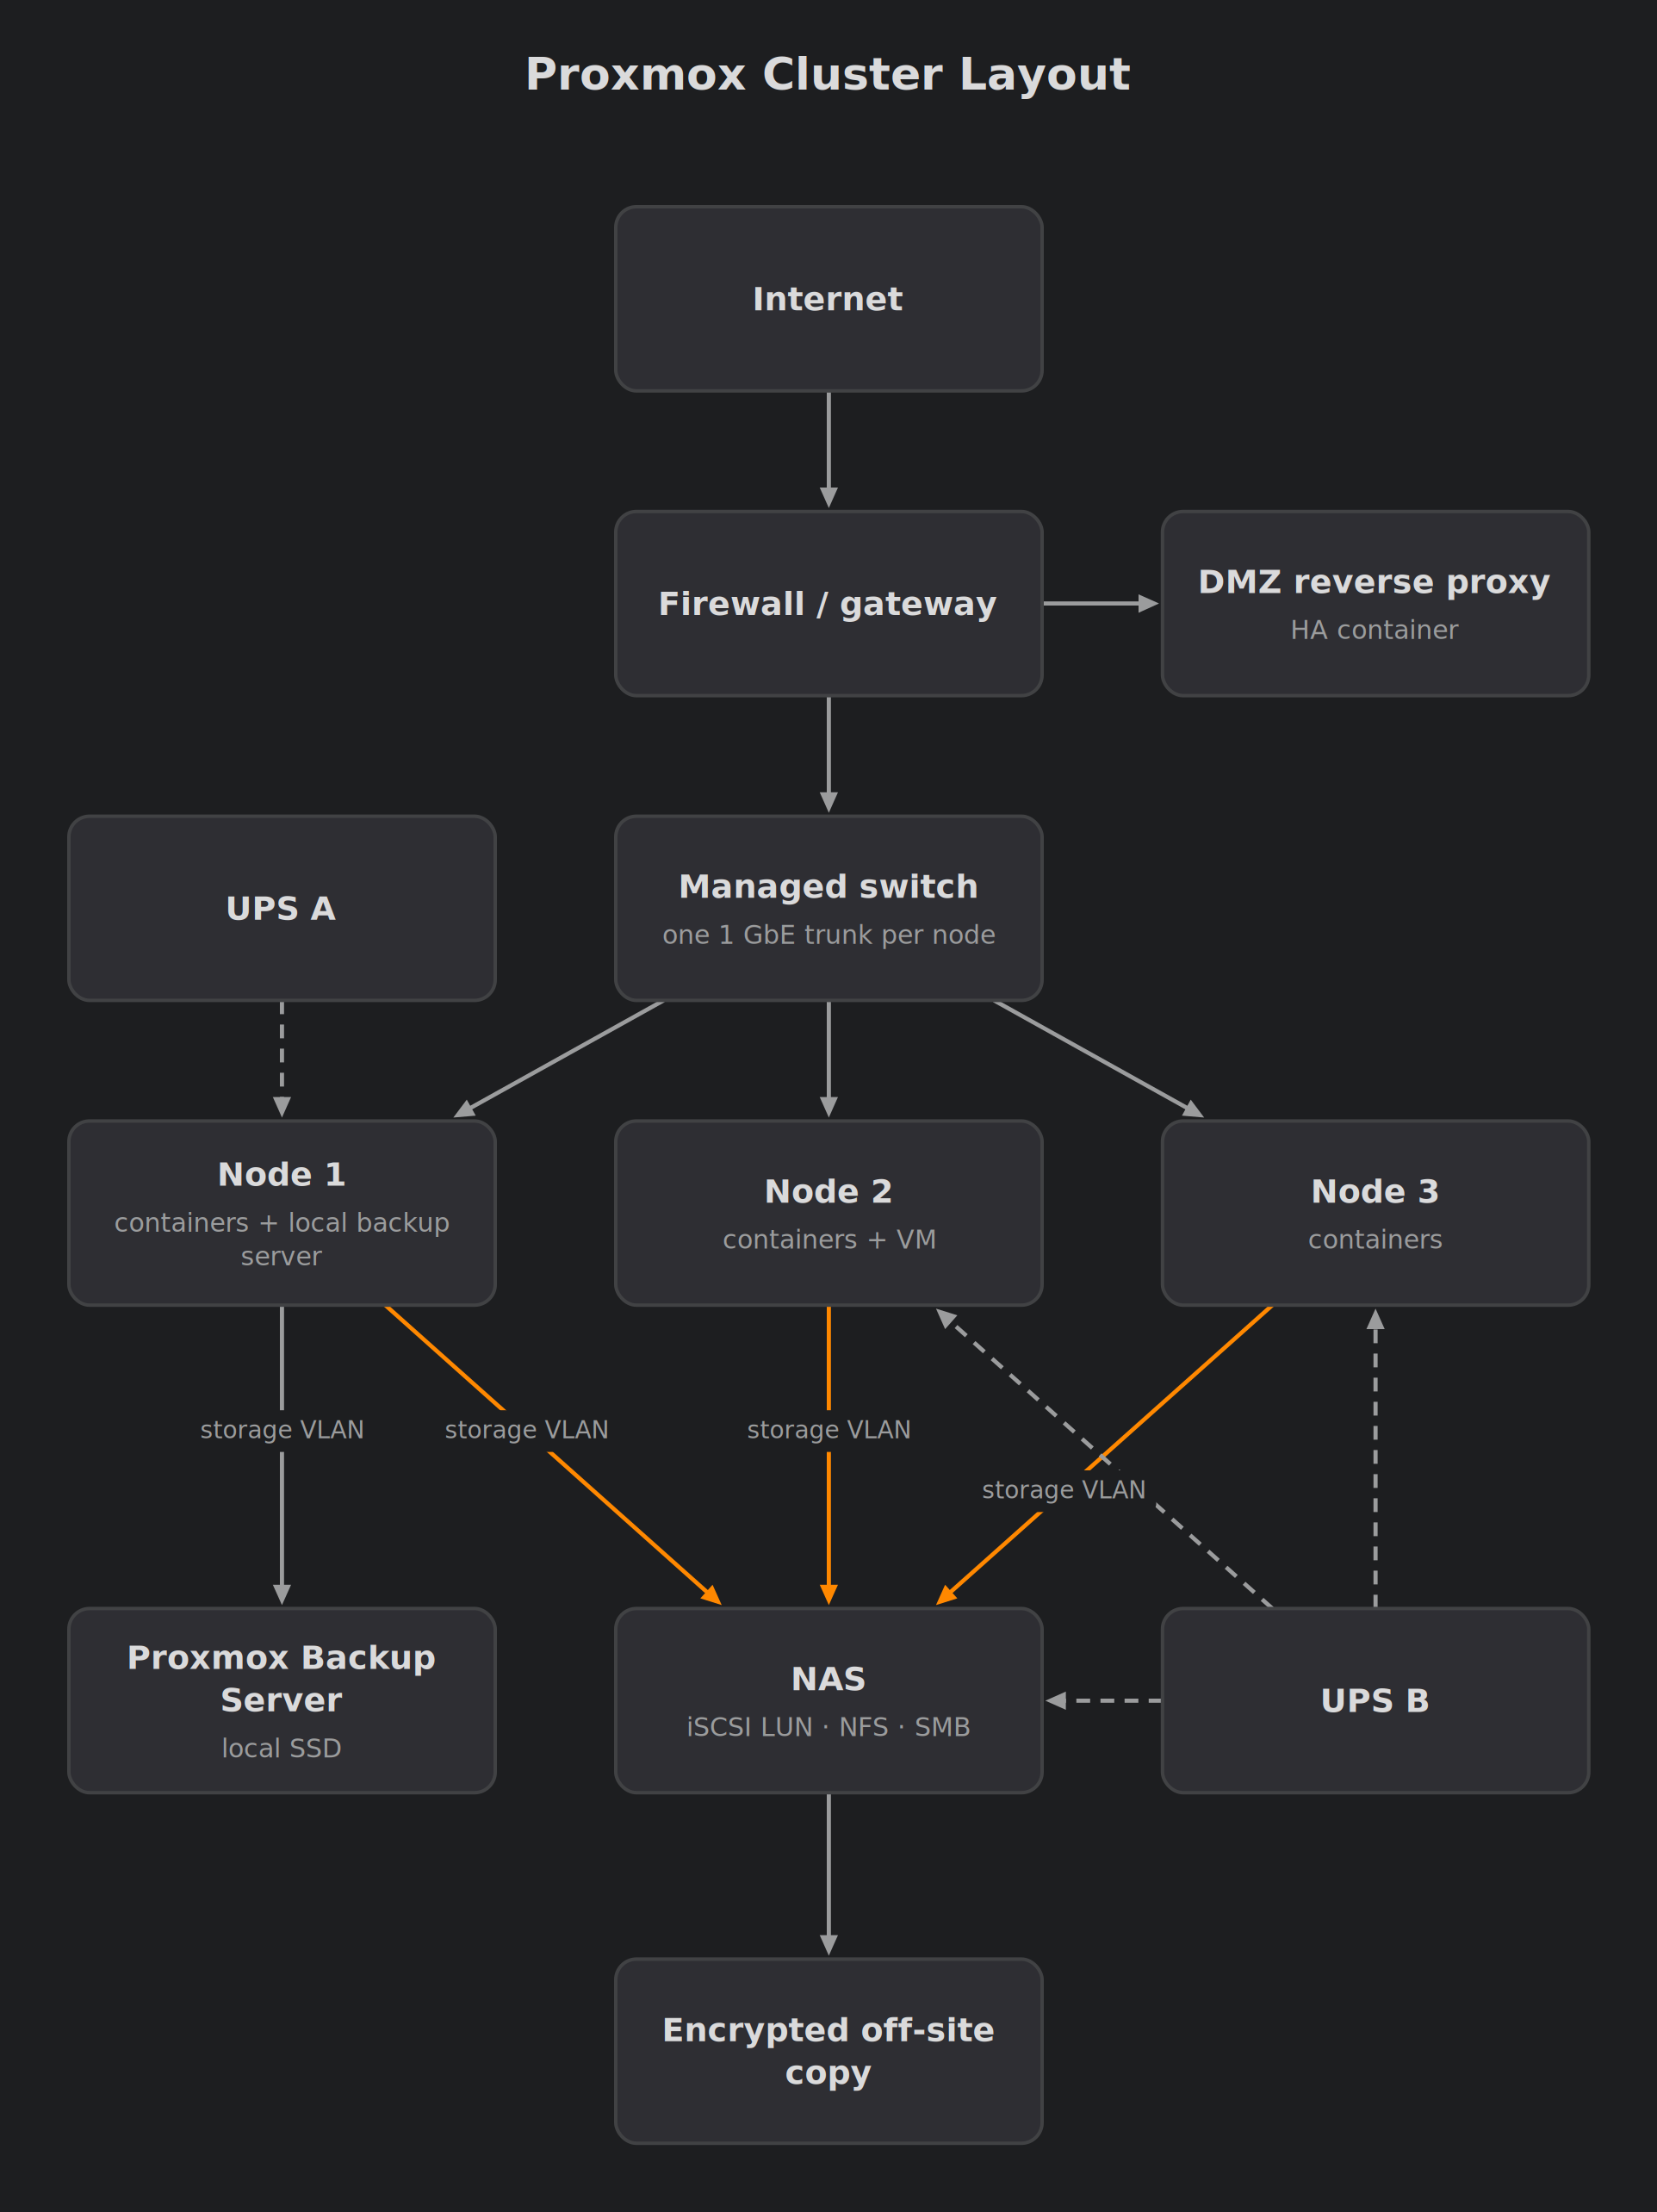
What changed: the original design had separate VLANs for iSCSI and for NFS backups, but both went to the same NAS port, so the split mostly added configuration. I merged them into one storage VLAN, then split them again once I noticed the NAS has two network ports: iSCSI now uses one NAS port and the NFS backups the other, each on its own VLAN. Guest disk I/O and the nightly backups no longer queue behind each other at the NAS. Neither storage VLAN has a gateway on the nodes, so storage traffic stays off the routed networks.
The iSCSI storage VLAN also carries a second corosync link. Both links share the same cable and switch, so this doesn’t protect against hardware failure. It does protect against the failure I actually had: a VLAN or port-profile mistake on the switch that cut the management network to a node.
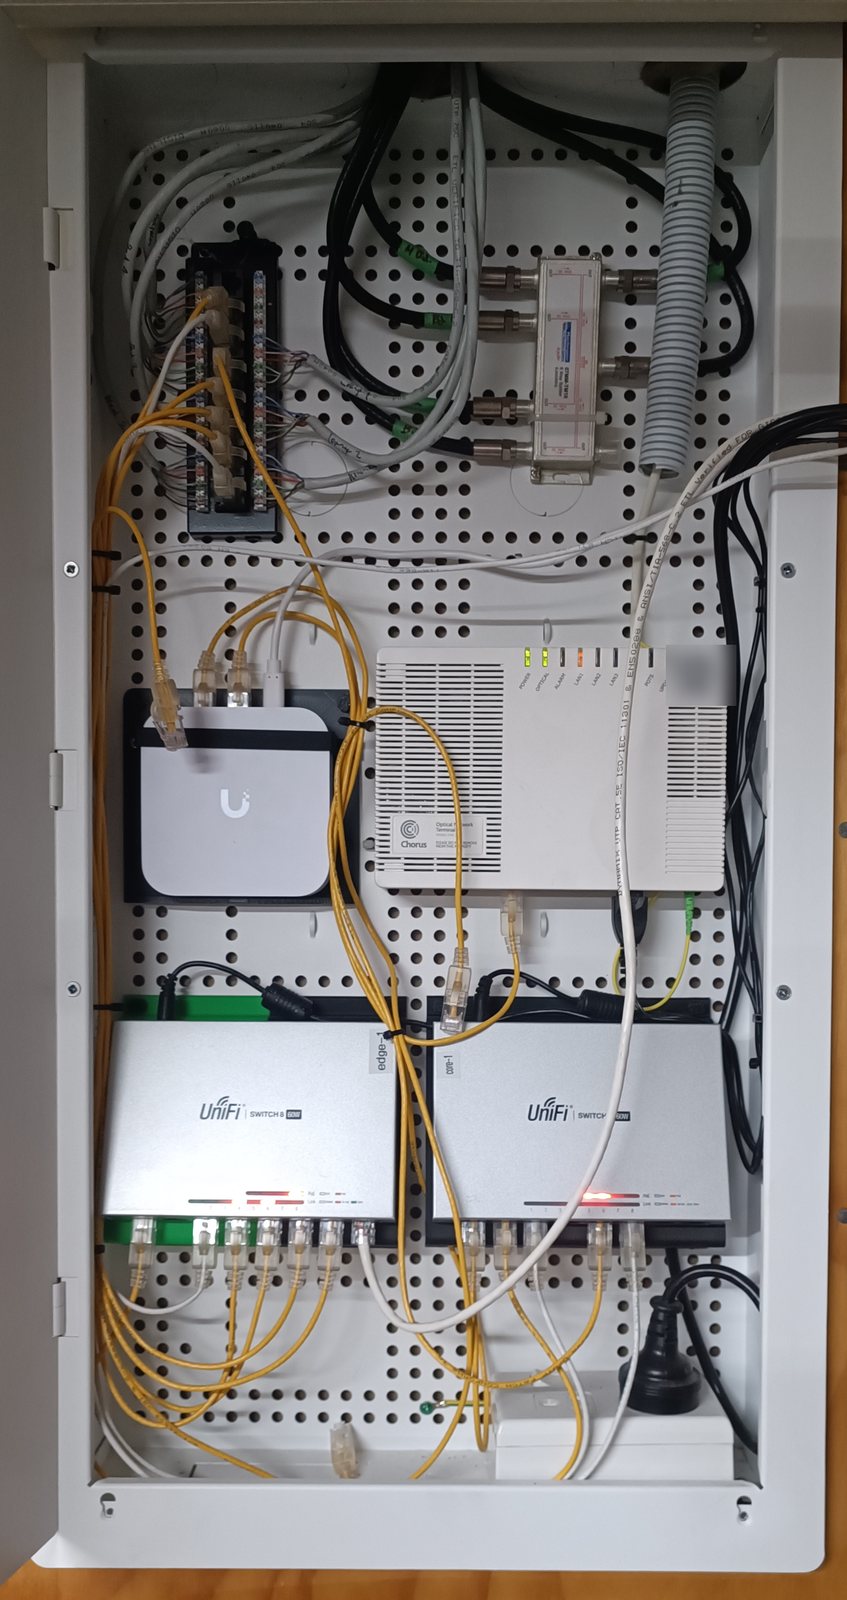
The network cabinet holds the fibre ONT, the UniFi gateway (the firewall in the diagram below), the core switch and a second edge switch. The house cabling ends on the patch panel at the top. Every VLAN reaches the nodes as a tagged trunk from here.
Storage Architecture
The NAS presents a 1 TB iSCSI LUN. Proxmox layers a shared LVM volume group on top, and 15 of the 20 guests keep their disks there. That shared storage is what makes HA possible.
The rest live on local NVMe: DNS, the monitoring/Docker host, the media server, the UniFi OS VM and the backup server. These are either too I/O-heavy for a shared 1 Gb link or must not depend on the NAS. The trade-off is that they can’t fail over. If their node dies, they are restored from backup instead.
Some details that turned out to matter:
- One iSCSI session per node, no multipath. With a single NIC, multipath buys nothing. Having two portal records, though, made Proxmox log in twice and show the LUN twice. I now change portals only with a script that tears the session down first.
- Boot ordering. The NAS boots more slowly than the nodes. A small systemd step makes guest start-up wait for the iSCSI volume group, and the iSCSI login retries indefinitely. After a full power cycle everything now comes up unattended.
saferemoveis slow. Shared LVM zeroes deleted volumes, at roughly 10 MB/s here. A guest stays locked until that finishes. Container disk moves are also file-by-file and offline. One container full of small files took 90 minutes to move, so estimate from the file count, not the size.
Workload Profile
The cluster is still almost entirely LXC. The one exception is the UniFi OS Server, which needs a VM. Containers share the host kernel, so they have small memory and disk footprints and light I/O. That’s the main reason 1 Gb storage networking is good enough.
The workloads are typical home-lab fare: DNS, a password manager, mail, a public reverse proxy, a Git server, monitoring (Prometheus, Loki and Grafana), web analytics and a media stack.
High Availability
Three containers are under Proxmox HA: the password manager, the DMZ reverse proxy and the mail server. These are the ones whose downtime I’d notice from outside the house. The UniFi controller, which was HA in the first version of this post, is now a VM on local disk and isn’t HA.
Lessons from running HA for a while:
- Use static resource-aware placement. I enabled the scheduler mode that accounts for RAM and CPU. Without it, failover happily piles containers onto the smallest node.
- The watchdog is real. A node running an HA guest arms a hardware watchdog. If it loses both corosync links for about a minute, it reboots itself. I make switch changes one node at a time, and I move HA guests away before working on a node.
- Stop HA guests before a planned full shutdown. Otherwise HA migrates them around as nodes go down, and they come back on the wrong node.
- HA covers a node failure, not a NAS failure. Every HA guest’s disk is on the NAS. That’s an accepted trade-off, and it’s why the backup design changed.
Backup Design
Originally, backups went by NFS to the same NAS that holds the primary storage. That’s convenient, but a single NAS failure would take out both the live disks and the backups.
The new design has three layers:
- A Proxmox Backup Server container on one node, with its datastore on a local SSD. It takes nightly, deduplicated backups of every other guest, and it doesn’t depend on the NAS. Backup traffic is pinned to the iSCSI storage VLAN.
- vzdump to the NAS over NFS. The backup server itself is protected here. Once the local backup server has a proven run of good nights, this layer moves to a weekly, lower-retention schedule. A small timer job flips that setting automatically and e-mails me the result.
- An encrypted off-site copy of the NAS backup share.
I’ve tested restores at each level: a container restored from the local backup server in about 15 seconds, and a file pulled back from the off-site copy.
Power and Monitoring
There are two UPSes. One is monitored over USB by a node, and the other by the NAS. Each node runs a NUT client and shuts down cleanly on low battery. The NAS’s NUT server allows only a handful of clients, which shaped which machines talk to which UPS. The cheap USB UPS also has a habit of hanging its USB interface, so I made sure “lost communication” alerts repeat until someone acts on them.
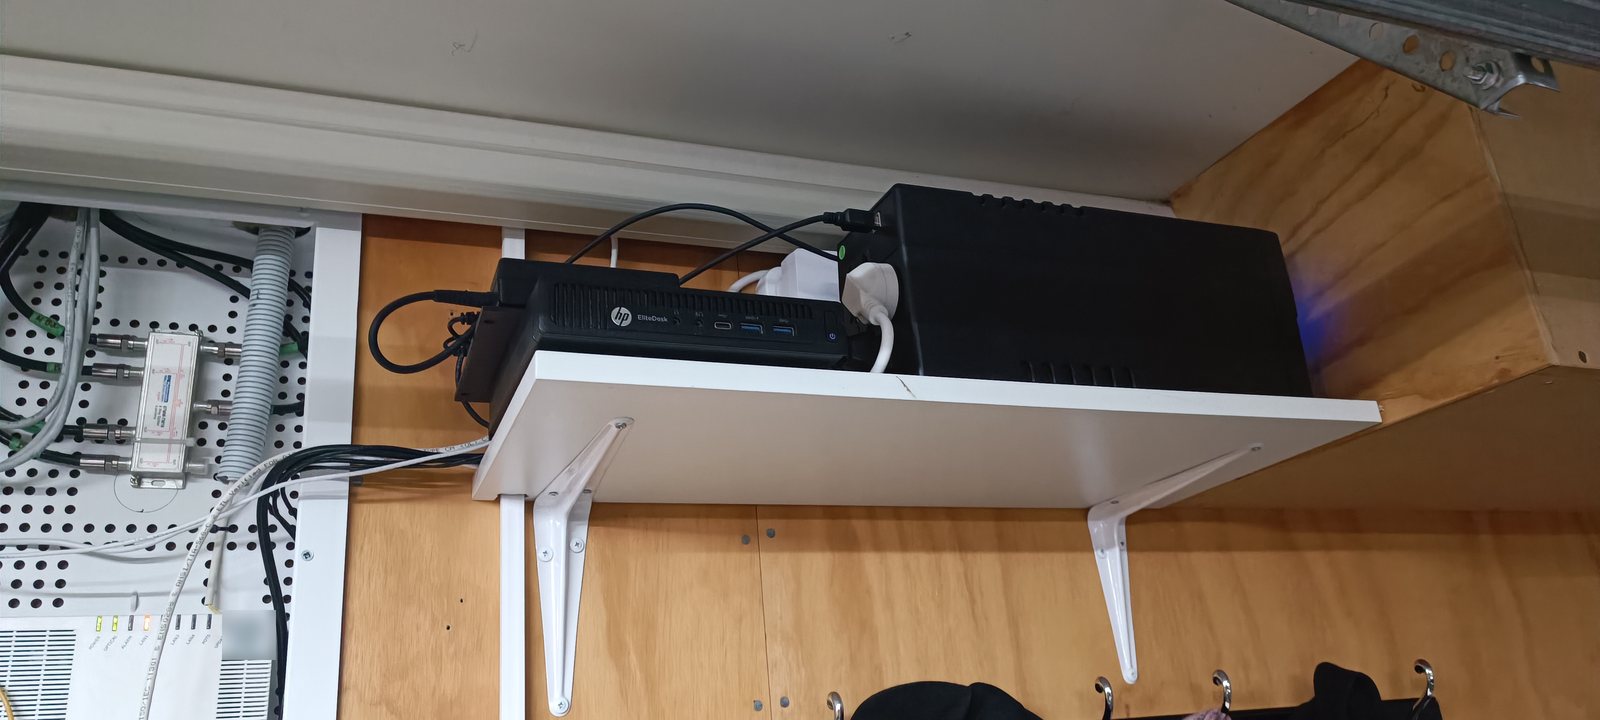
The third node sits on its own shelf next to the network cabinet, with the cheap USB UPS that it monitors. The other two nodes and the NAS share the NAS’s UPS.
Prometheus and Grafana collect node and cluster metrics. Containers that can’t run an agent forward warnings via rsyslog to Loki. Home Assistant gets a read-only Proxmox API role plus power buttons, deliberately not admin rights.
Tradeoffs
Advantages
- Cheap, quiet, low-power hardware
- Shared storage and HA for the services that matter
- Clean, simple VLAN layout
- Backups that survive a NAS failure
Limitations
- The NAS is still a single point of failure for most guest disks
- One 1 GbE link per node carries everything
- Redundant corosync links share one cable and switch
- Local-disk guests are restore-only, not HA
- Uneven RAM limits where things can fail over to
Lessons Learned
- Separate VLANs only pay off with separate paths. Two storage VLANs on one NAS port added configuration and nothing else; on two NAS ports they keep backups out of the way of guest disks.
- A second corosync link on another VLAN is cheap insurance against your own switch mistakes.
- Make boot ordering explicit when shared storage is slower to start than the hypervisors.
- Shared LVM’s safe-delete and offline container moves cost hours, not minutes. Plan disk moves for quiet times.
- HA without resource-aware placement will eventually overload your weakest node.
- Backups on the same box as primary storage aren’t really backups. A small local Proxmox Backup Server was the best change I made this year.
- Rehearse a full power-down and power-up before a power cut makes you do it.
The cluster remains right-sized: constrained, but stable, recoverable, and a good place to learn.
Comments